01
Clinical AI Evaluation
Understand performance where it matters clinically, including the nature and severity of errors.
- Clinical review of model outputs for accuracy, appropriateness, safety, reasoning, uncertainty and escalation, as relevant to the use case.
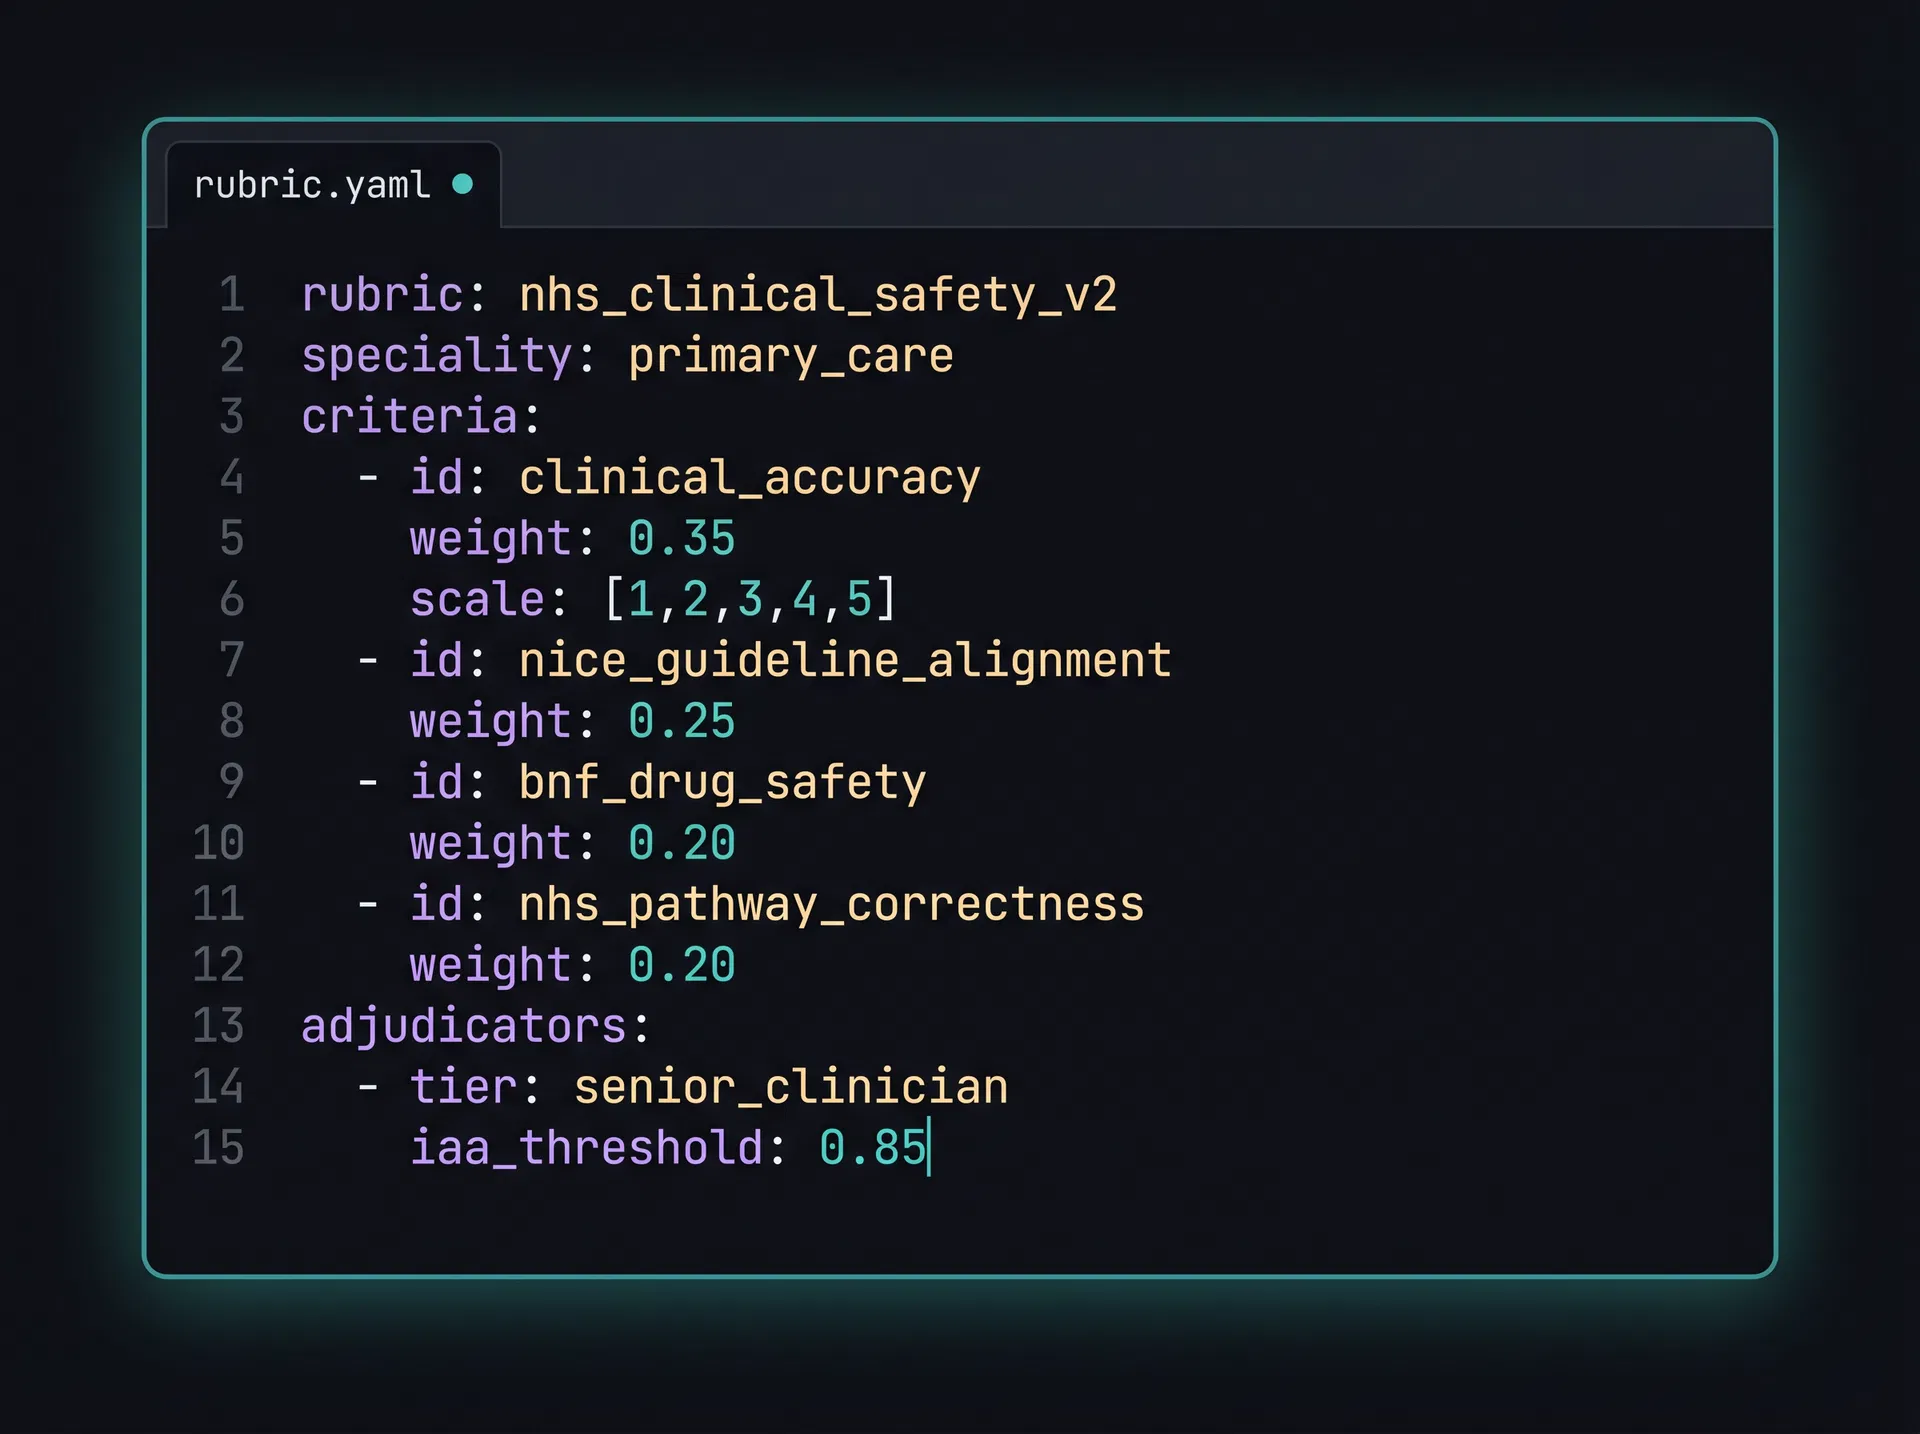
- Evaluation frameworks, scoring rubrics, error taxonomies and repeatable benchmark studies.
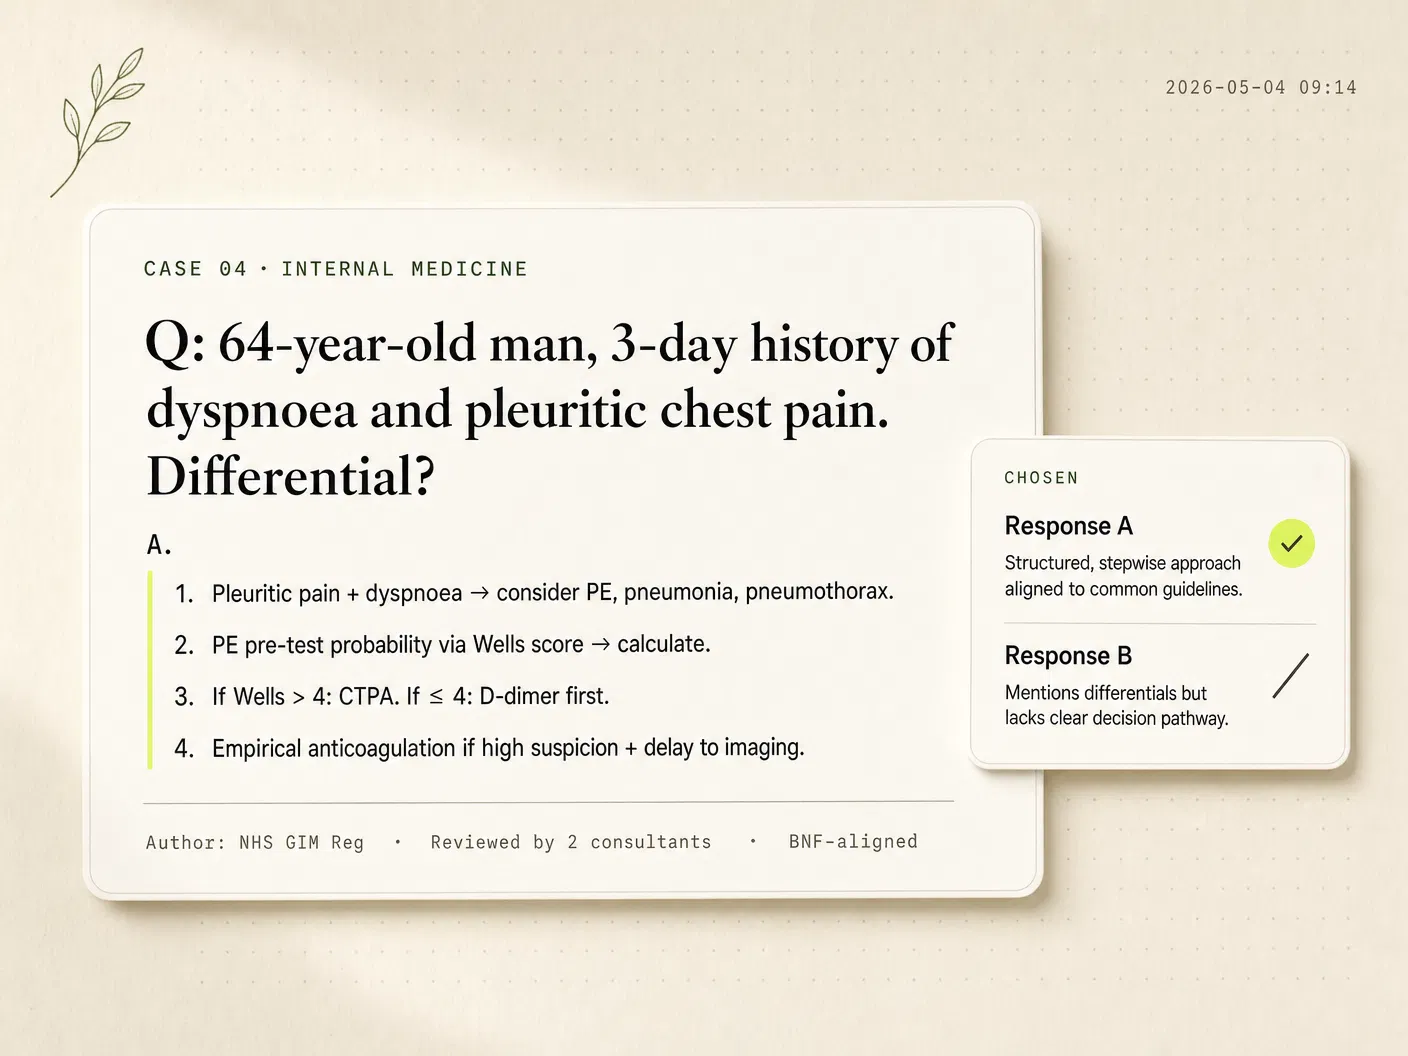
- Preference ranking and clinician feedback for RLHF or other preference-based workflows.
- Medical red-teaming, scenario design and analysis of failure modes.
- Structured findings that can inform iteration and, where scoped, a validation plan.
Typical outputsScoring criteria, reviewed cases, preference pairs with rationale, severity-graded issues, benchmark reports and prioritised findings. The exact deliverables are set in the project brief.